Banner reading “Moving the Dot: Where AI pays off in a privacy program,” with a glowing dot traveling along an arc across an abstract blue network toward the J.H. logo.
CCPA, CPO, GDPR, IAPP, Privacy, Privacy & data protection, Regulatory Compliance, Risk management

Moving the Dot: Where AI Pays Off in a Privacy Program

Executive Summary

Privacy programs have never been funded for full coverage. They close the gap between what the law requires and what they can afford by accepting risk. As pressure on obligations owed to individuals and regulators rises,1 that trade-off is becoming untenable.

AI changes the equation. Applied to four foundations of the program, and built on investments the enterprise has already made plus a targeted privacy layer, it acts as a force multiplier. It lets organizations reduce the risk they accept without a proportional increase in cost, provided it is managed as a control.

What You Will Gain From This Article:

1. Why Can’t Privacy Programs Cover Everything?

Meeting every statutory obligation and addressing every inherent risk has traditionally required more people than can be cost-justified. Programs close the gap the only way they can: they cover the highest-priority obligations well and tolerate gaps elsewhere. That gap is residual risk that has been accepted, often by default rather than by decision. And where it is a decision, it is often made by people with little real choice: privacy leaders without the budget or influence to close the gap.

Over time, that acceptance drifts. The question quietly shifts from “are we compliant?” to “how likely are we to be caught, or to cause harm?” That is an enforcement calculation, not a compliance one. It is rarely made explicitly, and it rarely survives an audit finding, a regulatory inquiry or an incident.

The economics have held because the only way to add coverage was to add people. AI changes that. Work that once required headcount, such as reading, classifying, searching and drafting, can now be multiplied, so less risk has to be accepted for the same cost.
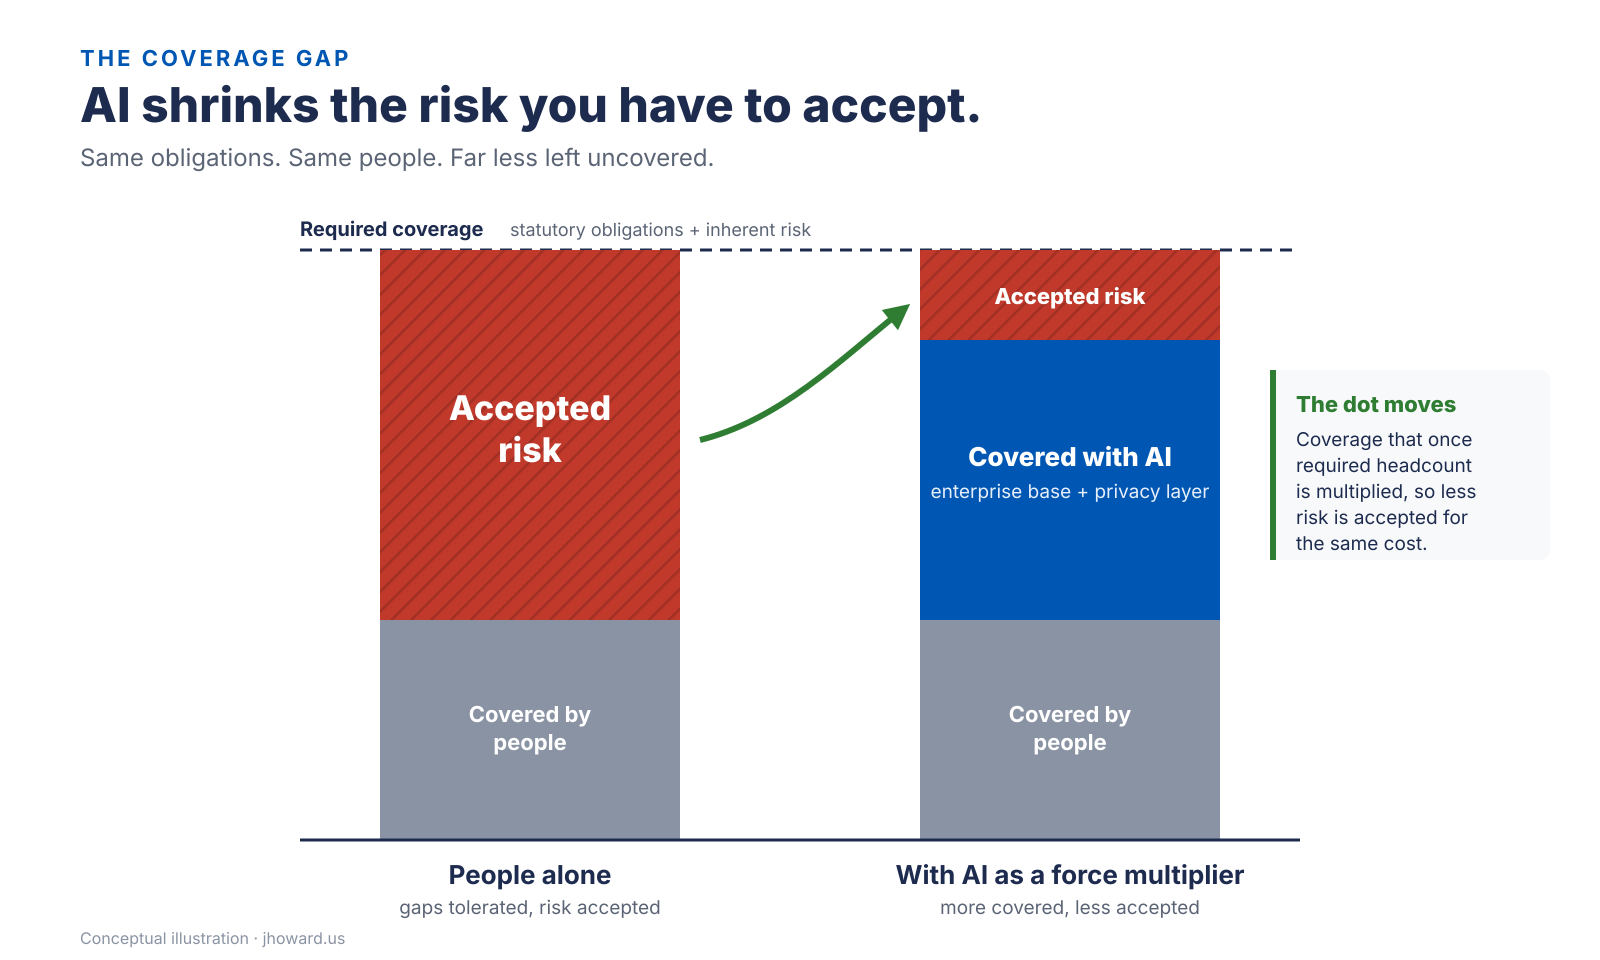
Two bars of the same required privacy coverage. With people alone, a large red block of accepted risk sits above a gray block covered by people. With AI as a force multiplier, a blue block covered with AI fills most of that space, leaving only a thin band of accepted risk.
Figure 1. The coverage gap: same obligations, same people, far less risk accepted.

2. Why Is the Gap Getting Harder to Sustain?

The gap is getting harder to sustain, particularly on the obligations side.

Rights requests are growing in volume, complexity and consequence. Individuals now use generative AI to draft long, legally sophisticated requests in seconds,2 and requests are increasingly organized: some are filed in bulk to gather material for litigation, and some opportunistically, to provoke a failure and claim compensation. Europe’s highest court confirmed in 2026 that a mishandled access request can itself give rise to compensation, even where the underlying processing was lawful.3 Every request, however it was drafted or organized, carries a deadline that runs from the day it arrives.

Incident rules keep tightening. The SEC’s amended Regulation S-P requires a written incident response program and notice to affected individuals within 30 days,4 joining the GDPR’s 72-hour regulator notification and a patchwork of state laws. Meeting those deadlines depends on knowing quickly whose data was affected and which rules apply.


3. What Are the Four Foundations, and Where Do They Sit?

Four foundations carry most of the obligations load, and they are not independent.

Two are reference foundations:

  • The data inventory tells the organization what data it holds, where it sits, and how to find a specific person’s records.
  • The rights and preferences profile tells it what each individual is entitled to and what they have chosen: consents, opt-outs, objections.

The other two are processes that depend on them:

  • Privacy by design (PbD) and privacy impact assessments govern change. PbD conveys privacy requirements before development begins, drawing on both reference foundations. The PIA confirms, after development and before launch, that those requirements were met.
  • DSR and incident response query both to define what must be searched, retrieved, disclosed or notified, and by when.
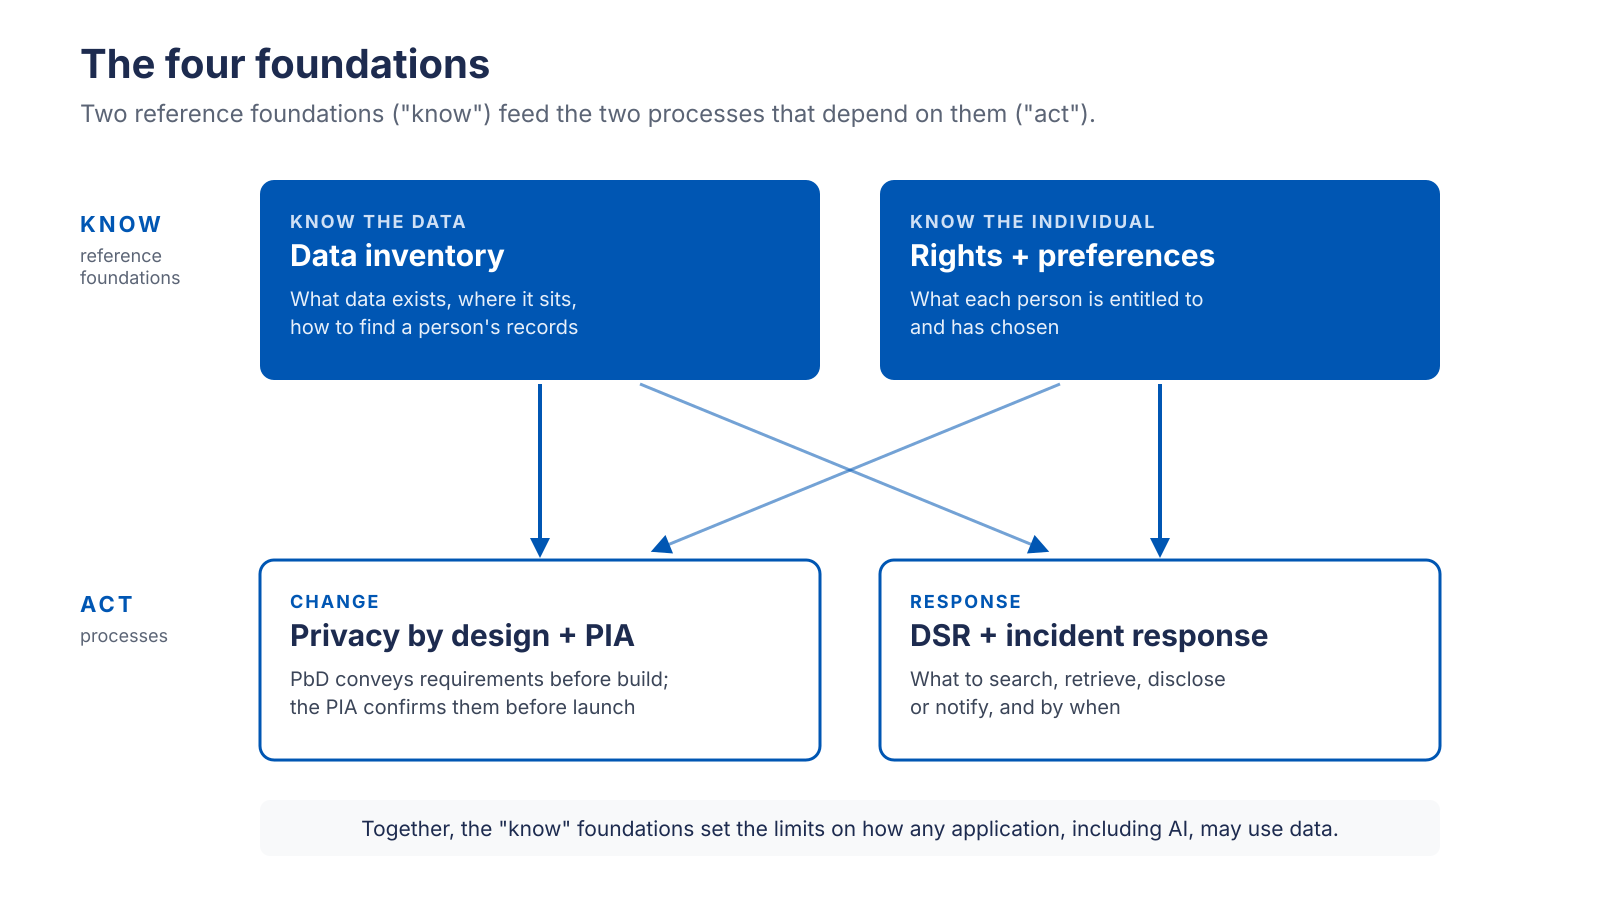
Diagram of the four foundations. Two reference foundations at the top, the data inventory (know the data) and rights and preferences (know the individual), each feed down into two processes below: privacy by design and PIA (change) and DSR and incident response (response).
Figure 2. The two “know” foundations feed the two “act” processes.

Plot each foundation by its residual risk and operating cost. Residual risk measures where each foundation sits; accepted risk is the part of it the organization is choosing to live with.

The Risk-Cost Matrix
Lower cost Higher cost
Higher risk Hidden exposures: cheap because under-resourced, not because well-run Pressure points: manual, high-volume, deadline-driven
Lower risk Steady state: standardized, automated, monitored Overbuilt: effort out of proportion to the risk it manages

In many organizations, the foundations sit like this:

  • Data inventory is often a hidden exposure: manual, rarely current, and too costly to cover the full breadth of the organization’s data. Application inventories often serve as a proxy, but their narrow view doesn’t support a common taxonomy or enterprise-wide classification.
  • Rights and preferences are often a hidden exposure, scattered across systems and markets. That’s cheap until an opt-out isn’t honored or a request is scoped incorrectly.
  • PbD and PIAs are often a hidden exposure that becomes a pressure point. Without requirements up front, issues surface late, and manual PIAs struggle to keep pace with Agile delivery. They are completed after the fact, forcing costly redesign (or more risk acceptance), or not at all, leaving a blind spot.
  • DSR and incident response are the pressure points: high-volume, deadline-driven, and inheriting every weakness in the reference foundations.

The hidden exposures are where risk acceptance lives. The pressure points are where it fails first. Rising pressure pushes every foundation up and to the right. The objective is to move them back, down and to the left.
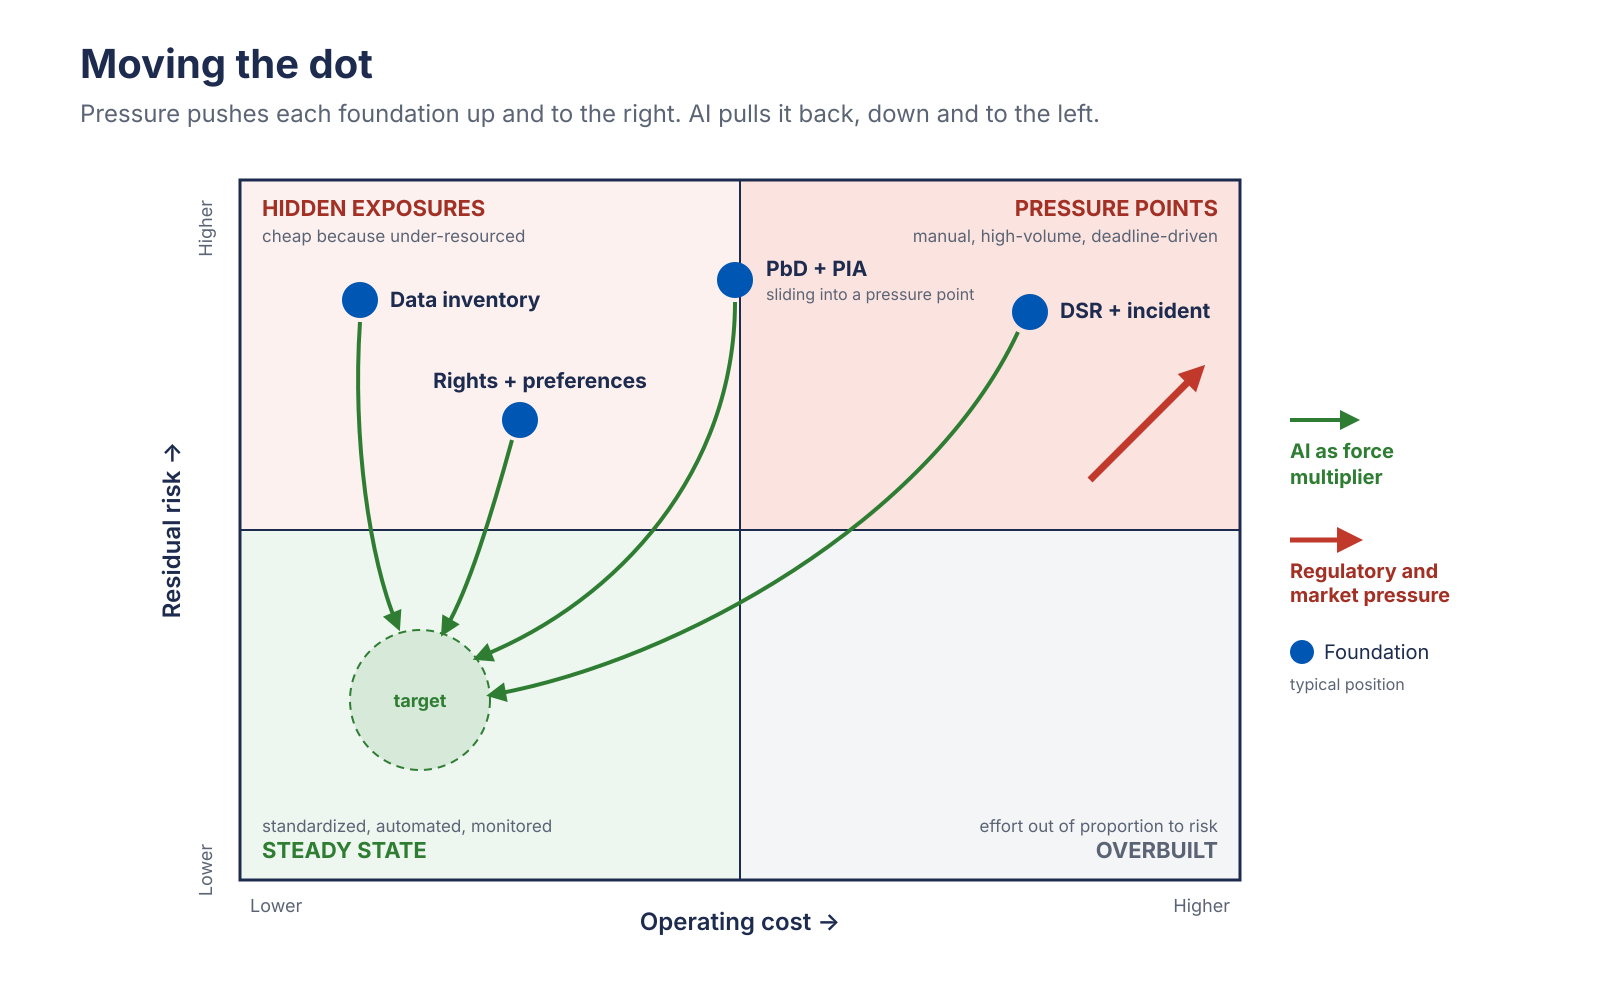
Risk-cost matrix with four quadrants: hidden exposures, pressure points, steady state and overbuilt. The data inventory and rights and preferences sit in hidden exposures, PbD and PIA on the border sliding into pressure points, and DSR and incident in pressure points. A red arrow shows regulatory and market pressure pushing up and to the right; green arrows show AI pulling each foundation toward a steady-state target.
Figure 3. Moving the dot: pressure pushes up and to the right; AI pulls back toward steady state.

4. How Does AI Change the Equation?

Most of the cost in a privacy program comes from people reading things: system documentation, call transcripts, emails, request letters, incident reports. AI is good at exactly that work. It can classify data, interpret a sprawling request, flag a likely rights request in a chat transcript, or draft a first-pass assessment, all for a person to confirm.

The enterprise is probably already paying for much of the capability. Security teams have invested in data discovery and incident management. Data teams run catalogs and lineage tools. Contact centers use speech and text analytics. Legal owns eDiscovery. Delivery teams run Agile tooling. Most organizations now license an enterprise AI platform.

But these were built for other purposes, and they rarely meet privacy’s needs on their own. A data catalog knows where data sits, not who it belongs to, what each person has permitted, or how long it may be kept. Incident management is traditionally owned by information security, with privacy running in parallel or added on afterward. The practical model is to leverage the enterprise base and add a privacy layer, which often means targeted investment in privacy management tools that bring privacy context to the platforms the organization already runs.

AI as a Force Multiplier: Leverage the Base, Add a Privacy Layer
Foundation What AI does Enterprise base to leverage Privacy layer to add
Data inventory Scans systems, classifies personal data, maps it to a common taxonomy, keeps it current Data catalogs and lineage, data security posture management, application inventories Privacy taxonomy and classification; links to individuals, purposes, legal bases and retention
Rights and preferences Interprets free-text requests and preferences, matches identities; rights determination stays rule-based Customer platforms, identity services A rights and preferences engine: jurisdictional rules, consents and opt-outs, propagated to applications
PbD and PIAs Generates requirements at intake; scans code for use of personal data and reconciles it with permitted purposes; embeds a short assessment in delivery tools; triages risk; drafts findings Enterprise AI platform, Agile and workflow tools, code repositories and CI/CD pipelines, GRC Privacy requirements library and assessment workflow integrated with delivery, linked to the inventory and rights and preferences
DSR and incident response Detects requests in calls, chats and mailboxes; automates retrieval; proposes redactions; reviews incidents for privacy impact Contact-center analytics, eDiscovery, security incident management, case management DSR orchestration; privacy impact triage and notification rules within the incident process

In each case, AI moves the foundation down and to the left: the enterprise base keeps cost down, and the privacy layer makes the risk reduction real. AI pays off first in the reference foundations, because every downstream process draws on them. Automating response on top of weak foundations simply produces wrong answers faster.

Privacy leaders see the opportunity but are moving cautiously. In a small 2026 benchmark, privacy ranked first of eleven functions on automation ambition and near last on trust in AI.5 Notably, the AI these leaders trust and use most is the AI embedded in enterprise platforms they already run, which is where the practical path begins.


5. How Should AI Itself Be Managed?

Using AI in a privacy program is defensible, and increasingly expected, but it introduces risks of its own: it processes personal data (including employees’), models make mistakes, third-party services raise disclosure and data-location questions, and AI regulation is evolving quickly.

AI is an assistant, not a decision-maker, and it must be managed like any other control:6

  • Foundations first. AI amplifies whatever it is built on.
  • Human in the loop for disclosures, denials, deletions, notifications and assessment outcomes.
  • Purpose limitation, with no drift into performance management or marketing.
  • Accountability for every AI tool: a defined role and limited permissions, a named owner, a record of what it did, and the ability to stop it quickly.
  • Architecture by design: run AI where the data already sits, and account for data location and emerging AI rules.

6. What Should Executives Do Now?

  1. Make the risk acceptance explicit, and elevate it. Identify where coverage gaps are being tolerated, whether that is a compliance decision or an enforcement calculation, and bring material acceptances to the operating or management committee and the board, where the authority to fund or accept them sits.
  2. Plot the foundations on the matrix using real indicators: request volumes, cycle times, missed deadlines, late or skipped assessments, audit findings.
  3. Inventory what you already own, and identify the privacy layer each needs: the catalog, security, analytics, eDiscovery, delivery and AI platforms the enterprise has funded.
  4. Strengthen the reference foundations first.
  5. Accelerate the pressure points with named workflows, starting with DSR and incident response and bringing PbD and PIAs onto the delivery critical path.
  6. Measure the movement: cost per request, cycle times, inventory coverage, PIAs completed before launch, and the risk no longer being accepted.

Two Questions for Boards and Audit Committees

  1. Where is our privacy program accepting risk today, and who decided?
  2. Which enterprise investments could support privacy, and what privacy layer would they need?

Conclusion: Moving the Dot

For years, privacy programs have balanced what the law requires against what they can afford, and closed the difference with risk acceptance. Rising pressure is making that balance harder to hold. AI does not eliminate the trade-off, but it changes its terms.

Built on strong foundations, investments the enterprise has already made and a targeted privacy layer, it lets organizations cover more while accepting less risk, without a matching rise in cost. Organizations that manage it well will respond faster, see their data more clearly, and earn the trust that turns privacy into a competitive advantage.


Notes

  1. This article focuses on obligations owed to individuals and regulators: rights, consent, change and incident response. Rising complexity affects program design and cost more broadly. New requirements must be translated into processes and applications across the enterprise, and programs also carry the cost of notices, third-party oversight, cross-border transfers, training and governance reporting. The same force-multiplier logic applies to many of these, but they warrant separate treatment. ↩
  2. Ireland’s Data Protection Commission reported more than 16,000 contacts in 2025, a 45% increase on the prior year, and noted that access requests are increasingly long and AI-generated. Data Protection Commission, Annual Report 2025. ↩
  3. Court of Justice of the European Union, Brillen Rottler GmbH & Co. KG v TC, Case C-526/24, judgment of 19 March 2026. The Court also held that clearly abusive requests may be refused, but only on evidence, and that refusing a first request should remain exceptional. ↩
  4. U.S. Securities and Exchange Commission, amendments to Regulation S-P (adopted May 2024). Larger covered entities were required to comply by December 3, 2025, and smaller entities by June 3, 2026. ↩
  5. Assemble, The State of AI in Data Privacy, Decision Intelligence Benchmark special report (survey of 26 data privacy leaders, February–March 2026). ↩
  6. AI proposes, people decide, accuracy is measured, and changes follow model governance. Organizations can keep AI close: on-premises, within their own cloud environment, or inside platforms they already use. They can also tailor it to internal data. Retrieval, where the model reads internal data at the moment of use, keeps personal data out of the model itself. Fine-tuning on personal data embeds it in the model, making the model a new repository that must be inventoried, secured and subject to individuals’ rights. As AI use grows, the reference foundations should extend to training data, models and agents. ↩
J. Howard logo

James I. Howard

CPO & Privacy Advisor

james@jhoward.us · More articles →

CDO, CPO, IAPP, Information Management and Governance, Information protection, Privacy

Looking Ahead: The New Operating Model for Business

COVID-19 has had a horribly disruptive effect on almost all people and aspects of society.  This paper starts a dialog around an admittedly tiny aspect of that and a view to the future.  It in no way should be seen to marginalize or trivialize the pain and suffering endured by the millions of people directly impacted by the pandemic.

On May 1st, CNBC published this article that discusses how some businesses are re-evaluating their need for physical office space in light of their experience with a majority of their workforce working remotely.

The rapid shift to work-from-home has served as a catalyst for change.  Many years ago, when video conferencing first became available, companies started to invest in equipment that was office-bound, hoping to reduce business travel. That never happened because the technology was temperamental, brands didn’t interoperate very well, there were never enough facilities, and the equipment required expensive point-to-point T1 lines.

Since then, there were advances in the technology along many orientations, including high speed internet to homes, corporate adoption of laptops, smartphones, and importantly, audio conferencing.  This enabled a shift toward work-from-home, and corporate shared office space – “hoteling” (universally adopted by consulting firms and hated by employees), smaller offices/cubicles sold euphemistically as “open concept” workspaces.  But many were still reluctant to use video (Dilbert summed it up well with a series of comics depicting people “working from home” taking video calls wearing their bathrobes).  Workers were far more comfortable with audio conferencing than video, but it still did a lot to get companies and workers more used to remote working.

The needle moved further toward remote workforce with the dramatic increase in off-shoring, leverage of contractors which in itself lessened the feeling of permanence of employment, and perhaps contributed to workers feeling more comfortable as individual contributors working from anywhere.  Paradoxically, there was a simultaneous shift toward urban living, as the number of young people wanting to drive or commute went down, which one might have thought would shift them back to offices.

Powerful Disruptor

All these shifts were gradual, and the net result was tidal shifts in the work model.  Leave it to nature to provide a dramatic disruption, which has resulted in remote working suddenly accounting for 95+% of non-essential workers.  The points raised in the CNBC article are not at all surprising, given how the experts are bracing for periodic reemergence of Corona, but are also supported by:

  • The high cost of commercial real estate and the need to manage costs
  • The remarkable advances in technology enabling remote working
  • The quality of life impact of time-wasting commutes

A shift to predominantly remote working has immediate benefits, including the opportunity to hire the most qualified workers without regard to their physical location, which helps address challenges businesses have faced hiring the right talent.  It also has consequences, such as the inevitable glut of empty office space.  The sudden reduction in the concentration of office workers has a significant impact to businesses relying on them – restaurants, shops, laundry, shoe-shine, even metropolitan transportation – as large portions of their customers stop coming.

Opportunities

In the past, there have been dramatic disruption to business leading to the shrinkage or elimination of entire industries.  Yet over time, business comes charging back.  Before Corona, unemployment was at record lows, and companies were clamoring for skilled workers.  This is after gloomy predictions of unemployment after waves of off-shoring everything from manufacturing to call centers to highly skilled workers.

What has to happen for remote working to become as effective as working from a managed location?

Physical space: Many people don’t have home offices and take over the dining room table instead.  This isn’t sustainable, since asking people to shift from a company managed location to home involves a level of disruption and the only financial beneficiary is the employer.   Wouldn’t it make more sense for the employer to provide each employee a remodeling budget (funded by savings resulting from reduced commercial real estate costs)?  Small contractors could build-out home offices based on guidelines or specifications defined by the employer.

Technology infrastructure: When someone works in an office, the employer provides a laptop and a portfolio of business applications, but also the infrastructure to provide access to those applications – physical connectivity, wi-fi, deskside support.  They establish standards that they are able to support in a cost-effective fashion.  This needs to be replicated in some fashion at home, at least for a portion of the workforce.  It’s not realistic to expect the worker to solve all their home technology issues and not impact their efficiency.  Solution?  A ramp-up of home technology service-providers (e.g., Geek Squad) who set up and support home offices.

Improved wireless: There is a race underway to roll out 5G infrastructure and public wi-fi 6 that promise high-speed performance that rivals (or beats) home-based/cable internet access.  This may be a boon for remote workers and their employers because it simplifies the support model by eliminating the so-called “last mile” connectivity to the individual house in favor of a more controlled infrastructure using transmitters on towers in public spaces.

Comforts and conveniences: As people get used to working remotely, their appetite for convenience goods and services will likely return.  This means the retail services that had been located near office buildings will cater to home-based workers.  To be sure, it won’t look the same, given that the density of customers is different.  There will be more home delivery or curbside service.  Will it be the same in terms of volume?  Probably in an overall sense, but the concentration will differ.  But it seems reasonable that the businesses that can cater to distributed remote workers will benefit.

Challenges – Privacy and Data Protection – a tiny slice

There is no doubt that as with any fundamental disrupter, there will be challenges to be met before we move to equilibrium – the so called “new normal”.  Among many others, information protection and privacy faces challenges.  Some years ago, a colleague authored a prescient paper entitled “Privacy in a Pandemic” that explored the reasonable tradeoffs to be made when balancing individual rights against the needs of society, famously captured by Spock as he sacrificed himself believing “the needs of the many outweigh the needs of the few… or the one”.  But the new equilibrium has implications for privacy and data protection in a more corporate setting.  While privacy regulation accommodate these priorities, privacy and data protection programs will have to re-calibrate their risk assessments and place new weight on risks made more prominent by the shift away from office-based workers, to one where the line between personal life and professional activity is blurred to the point where you can hardly tell the difference.  Clear desk policies went from being a constant real and philosophical debate to now being completely unenforceable, and therefore mostly moot.  Implementing sound technical controls that don’t disproportionately interfere with the ability to work will take time, and likely require new technology deployments.

Understanding purpose: A key enabler to pivoting data privacy will be a mature data governance program.  Making assumptions around higher level enterprise controls is no longer safe.  Instead, knowing the nature and location of data is far more important in order to protect while enabling use.  Providing more discrete permissions around the use of data will help lessen the risk of loss and unauthorized disclosure.  Understanding the purpose behind proposed use of data will enable assigning more discrete permissions.  Since preserving privacy is a lot more than just ensuring protection, the philosophy of understanding purpose also helps ensure appropriate use of data.

Fundamentals: Implementing new controls will take time and carries the risk of creating more frustration and confusion that benefit until the edges are smoothed out.  Privacy leaders should step back and consider the full breadth of their programs, leveraging all techniques to manage risk while avoiding unnecessary disruption.   An effective awareness program, for example, can go a long way to encouraging people to make safe decisions when handling data.

Summary

COVID-19 has created havoc in unprecedented ways, and has affected the lives of billions of people.  The human toll cannot be measured, and the suffering by so many should not be swept aside.  Experts are working through the optimal medical strategies while economists are still trying to model the short, medium and long term impacts to business.  Entire books will be written and college classes will be structured around the Coronavirus pandemic.  This paper has taken a very narrow slice of that and will hopefully start an open-minded dialog around how to help enable the future operating model for business.  The dialog can and will continue in months and years to come.

CCPA, CPO, GDPR, IAPP, Information Management and Governance, Information protection, Privacy, Risk management

Why do we have such a hard time understanding, assessing and managing risk?

Introduction

Risk is a real concept that manifests across life.   Within a business context, risk management is a valuable tool to help improve the probability of success.  This paper explores the role of a risk manager, and is applicable across the board – whether business processes, technology, security, privacy, information or enterprise.  The reader can easily extrapolate the ideas to any aspect of life.

Definition and Reporting

Definition of risk: The probability or threat of quantifiable damage, injury, liability, loss, or any other negative occurrence that is caused by external or internal vulnerabilities, and that may be avoided through preemptive action.

The key word is “probability” – the likelihood that the event will occur.  In some instances, that can be calculated empirically, if all inputs and effects are known, where triggers can be identified – even if random (roll of the dice).  Other times, probability can be estimated based on historical data around similar conditions (50% chance of rain).

Other times, especially in business settings, there are more variables than can be practically tracked and quantified.  In those settings, Risk Managers use judgment to assess the risk of an event occurring.  The risks are usually classified in a 3 or 5 point scale – say, red, yellow, green or severe, major, moderate, minor and insignificant.   And the more knowledgeable the Risk Manager, the more insightful their assessment of risk, but it still remains a probability.

Challenges

Communicating risk gets complicated when we start factoring in risk mitigating strategies – avoid, reduce, transfer, accept—and reduction techniques – controls, TOD/TOE, residual risk, control risk, etc.

Even within the mitigating strategies there are grey areas – avoiding has consequences (lost opportunities), acceptance doesn’t mean the adverse event will occur, reduction doesn’t mean eliminate.

While some leaders claim they are comfortable navigating uncertainty, there is no question that business hates risk: markets react to uncertainty, and “punish” companies that operate with too many unknowns, and reward those that demonstrate clarity.

People publish dashboards and discuss numbers of controls, as though they were currency – more controls must be better – even though one good (strong) control could replace many poor (weak) controls.  Even auditors are reluctant to rely on process controls and would rather verify every transaction instead (assuming they could).

So what’s the issue?

To some extent, we, as Risk Managers, are the issue.  When asked about risk, we articulate it in our own language:

Risk Manager to Client (or internal business stakeholder): “there is a risk that such-and-such could happen that has these consequences”

Client: “how likely?”

RM: “moderate”

Client: (thinks: “huh?”) “what can we do about it”

RM: “implement x-y-z control”

Client: “will that make it go away”

RM: “implementing this control will reduce the risk, but it leaves a residual risk”

Client: (thinks: “huh?”) “Is that a ‘yes’?  Why wouldn’t you just do it?  And what’s that mean?”

RM: “here – sign this ‘residual risk acceptance document’”

Client: “ok – done”.  (thinks: “thank god that’s over!”) Back to business as usual.

Let’s face, this exchange isn’t very helpful.  The Client clearly doesn’t understand the risk as a potential impact to his/her business, and the “residual risk acceptance document” is a rubber-stamp.

Who owns the risk?  Risk Managers say that their business process stakeholders own the risk, and the Risk Manager’s role is to explain the risk, options for control, and residual risk.  However, it’s fair to say that the business process stakeholders often doesn’t truly accept their role, or if they did, they would engage in a more meaningful dialog.  And the residual risk acceptance document effectively nullifies the dialog.

If the controls are effective, or for whatever reason, the risk fails to manifest, then what?  How often does the client step back and acknowledge that RM did their job and issues were avoided?  Or does the client question why the risk management exercise was undertaken?  On the other hand, if an adverse event takes place, despite controls, does the client look at RM as though they failed?  The cynical reader would point out that if the on-going processes of managing risk management were part of core operations, then you wouldn’t see a spike in RM funding after an event takes place; you might see some refinement or realignment, but not a huge uptick in funding…

An alternative approach

So the challenge is how to meaningfully communicate risk to leadership in a way that puts risk in a business context.

First, one must keep clear: generally speaking, risk can’t be eliminated if the business wants to undertake the activity that introduces the risk.  That said, the Risk Manager can keep the following in mind as these points might promote meaningful communication:

  1. Articulate the risk in familiar business terms (“speak English!”). Explain what would have to happen to trigger the risk.  If you describe a chicken-little event without explaining the triggers, you might get dismissed.
  2. Be realistic when describing the risk and the likelihood. The likelihood should include realistic related events.
  3. Propose options for mitigating the risk, including avoid-reduce-transfer-accept. Bring a reasonable amount of research to present viable options, and be able to articulate the residual risk.
  4. Understand appetite for risk at an appropriate level. A mid-level manager may have a different appetite for risk than the CEO.
  5. Consider what kinds of risks needs to be escalated and to what level: Don’t present a risk to a CEO in a “Enterprise Risk Management” setting that should be addressed by a mid-level manager.
  6. Be realistic in evaluating the consequences of the risk. Walk the stakeholder through understanding the various consequential outcomes to help determine an appropriate mitigating strategy.
  7. Make clear who owns the risk. Get rid of “risk acceptance” documents – if a risk is significant enough to warrant action, it should be pursued.  Risk Acceptance documents are an attempt to shift/assign responsibility, and if they are needed, then they will also be ignored in the post-mortem.
  8. Acknowledge that business environments are dynamic, and events rarely unfold negative risks occur. People intervene.  Processes engage.  The outcome is rarely what was predicted when the risk was recorded.  And the more catastrophic the risk, the more it morphs as it unfolds.

Many of these considerations apply in the post-mortem stage.  One of the big challenges in the risk management community is one of appropriate hindsight.  When evaluating changes to make in risk management in light of an event, it’s important to remember what was known and considered at the time risks were assessed.

The overarching themes in this article is that risk managers need to be realistic when articulating risks, consequences and controls.  Risk managers must recognize they need to bridge the communications gap to their stakeholders by describing risks in business terms that will resonate.

Risk is a fact of life in every aspect of business.  Bad stuff happens, and risk management is not risk “elimination”.  Risk managers play a critical role, and by thoughtfully supporting their stakeholders, they can help business accelerate forward.


CDO, Information Management and Governance

When do data-dependent startups need a Chief Data Officer?

More and more startup companies are exploiting business opportunities tied to data.  Whether developing data-dependent AI, re-imagining how to conduct familiar business processes in innovative ways, or intelligently designing and building datasets drawing from a growing variety of sources.  The common theme for this class of business is the reliance on, and exploitation of, data.

In the earliest stages, startups are focusing their energy and time on creating their product or service.  As they begin to mature, they naturally start to move toward a state where they are returning value to their stakeholders – profits.  Perhaps they plan an IPO or to be sold to an investor, or some other larger entity.

This paper explores options and approaches that companies could consider to determine if and when they should appoint a Chief Data Officer (CDO), as well as their scope of responsibilities.

What kind of startups should prioritize appointment of a CDO?

At some point in their lifecycle, any company that is dependent on data will need to implement data management processes.  These include processes to acquire, ingest, catalog, track and at some point, dispose of data. If the data is licensed or belongs to others, they will need to understand and comply with applicable obligations.  They will need to create a data architecture, build repositories and apply appropriate controls to protect the data.

This description admittedly covers a lot of scope.  So the following adds a little structure to the thought process:

Does the startup…

  1. Handle large volumes of data?
  2. Have data as core to it’s business, where completeness, accuracy and currency are critical?
  3. Have products and services that are dependent of data, but are themselves not data products?  (e.g., a website or app with data in the back-end vs. a licensed database)
  4. Need data that is licensed or procured from others?  
  5. Use personal data (PII) or health data (PHI)?
  6. Need to demonstrate data lineage or provenance?
  7. Create new data, which has intrinsic value?
  8. Live with the risk that a data incident could cause irreparable harm?

If the answer to many of these are Yes, then the company should consider appointing a CDO.  Moreover, if the company wants to go public or be bought by another company – especially a public company where the transaction is material, the startup may be expected to demonstrate discipline around the treatment and protection of data, including documented policies and procedures.  While a CDO isn’t necessary to do this, a CDO can design and implement practices and disciplines that will provide comfort in a due diligence setting, and integrate those disciplines into the daily business routine of the startup.

What value can a CDO provide to a startup?  

Removing Barriers:

A CDO can provide a range of value to a startup.  The CDO looks at a company’s business through the lens of data, and is sensitive to both the value (revenue) cycle as well as the risks and obligations, recognizing they go hand-in-hand.  From this vantage point, they can enable the business by sourcing data and removing barriers, and can implement right-sized controls, proportional to actual risks and obligations. In effect. they can enable the data scientists – who seem to always “need…more…data…” – by providing relevant data, aligned with business objectives, where obligations and risks are managed elsewhere.  Call it “unencumbered data”.

Scientific Method:

A CDO understands and recognizes the transformative potential of data, but also a balanced sense of proportion – especially when resources are scarce.  By implementing structure around the activities of data scientists, a CDO can improve the chances that research will be fruitful and aligned with business objectives – with a necessary degree of transparency for stakeholders.  

Protection and Compliance:

Most information that companies want to use will have some kind of requirements around handling.  These will emanate from one or more of the following:

  1. The data is regulated; many data projects will incorporate information about people — PII or PHI — likely controlled by one or more regulatory frameworks (e.g., GDPR, CCPA, GLBA, HIPAA/HITECH)
  2. The data belongs to others and is governed by a contract or Data Use Agreement
  3. The data is valuable and needs to be protected – these protections might be present as a result of the data being regulated.
  4. A breach of the data could result in harm or loss, either to the company or to data owners, and should cause the company to respond in a certain way.

The CDO, who should understand the nature of data, can work with the CISO and counsel to implement proper controls to protect the data and comply with requirements.

Ethics:

By understanding the business and compliance perspectives of data, the CDO can provide perspective on the ethics of data use.  So much of the new digital economy is exploring uncharted territory, where potential uses haven’t yet been imagined. There are lines not yet drawn around what industry should do, even though they can do it.  Data-driven inventions can cause real or perceived harm to consumers as they disrupt industries.  Whether its financial services, advertising/marketing, insurance, consumer electronics, or the breadth of online applications and properties.  Data is central to these and a misstep can be catastrophic.

Optics:

Transparency is a cornerstone of the capital markets.  And while data-driven startups are inventing new ways to conduct business and benefit consumers, much of it is betting on the future.  With so many unknowns, appointing a CDO can help inspire confidence that a data-dependent startup is approaching their objective with a view to managing their data assets for the longer term.

What can a CDO do?

85% of the time, “Big Data” initiatives fail to meet their objectives, and 50% of startups fail in the first year.  Start-ups relying on data can’t afford many false starts. The CDO can spearhead data management activities that can, in aggregate, reduce risk of project failure and increase the likelihood of achieving the desired outcome.  These might include

  • Vision and strategy, involving leaders across the company
  • Data inventory
  • Data architecture
  • Data acquisition
  • Data maintenance and quality
  • Data retention and disposition,
  • Risk assessments, protection and compliance processes

While these are not necessarily discrete activities, and should certainly be scaled to the situation, having a framework in place would be very useful to (1) enable growth, (2) permit introduction of different data sets, and (3) give Boards of Directors, auditors, reviewers and regulators a level of comfort that the company takes data management seriously.

Balancing cost vs value?  Alternatives…

Many early stage startups are focused on laying out the important initial groundwork to sustain themselves — developing products, recruiting talent and identifying customers.  As they move through funding stages and become established, they might be looking toward aggressive growth, IPO and engaging in discussions to be acquired. This is a sliding scale – and it may not make sense to appoint a full-time CDO initially.  Startups should consider engaging a consultant or a CDO on a contract basis to implement and appropriate framework. As time and circumstances evolve, the time commitment can be adjusted.

Who should drive the decision?

The role is so important and strategic, that the CEO should drive the decision to appoint a CDO.  The CDO should expect to work closely with the CEO, as well as the rest of the executive team. Moreover, the CDO should expect to meet with the investors and advisory board to reinforce the role and how it will help the company accelerate forward.

Conclusion

It goes without saying that startups leveraging data science are not at odds with managing data, or the scope of a CDO.  They are extremely complimentary, to the point where an CDO can dramatically improve the probability of a data program, or data-dependent startup, succeeding.  

CDO, CPO, Information Management and Governance, Information protection, Privacy

CDO’s Role in Managing Data Breaches

In the span of a week, we’ve see data breaches affecting 600 million people.  For perspective, that’s more than every man, woman and child in the US, Russia, Canada, Britain and Australia combined.  And the damage may not be done, as scammers and other bad actors frequently take advantage of the widespread confusion that follows these sorts of incidents.

Moreover, as the investigations unfold, we will begin to see the breadth and depth of what went wrong, who did what, and what steps must be taken to prevent this from happening in the future.

The risk manager in me says this will happen again, just as it’s happened before.  Data experts know all too well the challenges in implementing controls proportional risk, and counter-balancing every data initiative with the right set of controls — starting with asking whether the proposed data collection or use benefits are worth the downside risk.

So what does this mean to a Chief Data Officer?  In a word, everything. Why? Because data is at the center of every breach, and the CDO should be looking at the full picture around both data use and data risk.  The emerging role of the CDO in business positions them as a key executive in helping to reduce the risk of breach as well as to navigate the aftermath, protecting the organization’s brand.

Before a Data Incident

In the normal course of business, the CDO should be executing against the company’s data strategy and vision, and maintaining an inventory of critical data assets.  The inventory should include key meta-data — ownership, obligations, location, permissions, value, uses, etc — which forms an important part of a periodic risk analysis.  

The risk analysis considers threats, vulnerabilities, obligations and relative value of the data to conclude on appropriate protections.  The more progressive CDO’s will construct a holistic threat analysis that answers the question, “what could go wrong?” or “how might information be breached?” taking into account behavior of personnel, company culture, key business activities and positioning of the company in the marketplace.  Typically, such an analysis covers the spectrum from the seemingly mundane (accidents caused by carelessness or poor judgment), all the way to industrial espionage targeting company data, with a total of 5 or 6 categories in between. This analysis serves as a sounding board to validate the range of control activities, which includes everything from policy, to business practices, to training, to technical controls, and some instances where certain risks have to be accepted, insured against, or perhaps transferred elsewhere.

The CDO should provide business requirements to the CIO and CISO for appropriate technical measures to provide protections, which – depending on the sophistication of the company – could range from providing data classifications, to which the CISO or CIO react, all the way to explicit requirements for, say, encryption and access control.  

The inventory shines a light on whether all data on hand is truly necessary, or whether some can be disposed of.  Moreover, the CDO’s analysis of business processes using data can also question whether all data being collected is necessary.

The Board of Directors, senior executive leadership and internal audit should – to appropriate degrees – be aware of how the company is using data as well as the CDO’s assessment of risk and mitigating controls.  This will allow them to understand the risk/benefit around data use, and weigh in whether the business opportunities related to data use are sufficiently compelling.

The CDO maintains relationships with counsel to understand the legal aspect of obligations, and obtain sign-off on the sufficiency of the compliance programs.  The CDO should understand their regulators’ expectations and requirements around handling data, making sure their protection controls meet regulator expectations.  These steps are key, because most breaches — especially where regulated data is involved — will result in legal or regulatory exposure, and having transparency with counsel and regulators with streamline investigations.

The CDO should own (or be a key stakeholder in) the data incident management process. This is the process whereby data incidents — data loss, possible breaches or exposures — are logged, analyzed and investigated.

During a Data Incident

Sometimes, a target organization is aware of a data incident as it’s occurring.  Many companies have processes to respond in this event, which may focus on containment, interruption, or other priorities (allowing an attack to proceed in a controlled way may help law enforcement with their investigation).

The CDO should be available to help answer questions about the nature and location of data that may be accessed, as well as to begin preparing post-incident planning. Some data owners (e.g., Federal Government) have explicitly defined time frames to report data incidents, the CDO can get ahead of these requirements.  

Following a Data Incident

Companies should have a crisis management plan that includes defined procedures to be followed in the event of a cyber attack, data breach or exposure.  The details of these plans are tailored to each company, and generally emphasize damage control and protecting the brand — which in itself may follow one or more tracks, based on the nature of the incident.  

Stakeholders include senior leadership, legal counsel (sometimes supported by outside counsel), the head of security, the CIO and CISO, and often on-call cyber security consultants.  The overall objective is to understand what happened, how it happened, who perpetrated the event, what data was affected, overall impact, and how to repair the damage and prevent the same thing from happening again.  

Along these lines, the CDO should help assess the impact of the loss, in terms to cost to the company — defined as asset value, or competitive impact, or brand damage to the organization.  The CDO can be a resource to analyze the nature of the data to determine whether external notifications are required, and – in conjunction with counsel – whether there is a regulatory impact.  Who owned the data? Do regulators, customers, vendors, partners or clients need to be notified? Is there a timeframe requirement for notification and is there a specific process to be followed?  Do affected parties need to be offered – or are they likely to demand – compensation?

The CDO can help analyze what went wrong, by having an understanding of the processes and policy around data use.  Was there misuse of data or was it stored, processed or transmitted in ways it shouldn’t be? Was there a control failure, or absence of control?

This analysis concludes with a reassessment and remediation of processes and controls.

Conclusion

Most corporate leaders recognize the near-inevitability of a breach or hack.  This is due to a variety of factors, including the increased complexity of information systems, coupled with the expansion of data-rich cognitive and robotics initiatives, many of which rely heavily on data.  Data sets themselves are growing at a dramatic pace.

Companies are appointing CDO’s to try and coordinate the activities around the leverage of data, and increasingly, they are assigned responsibility for assessing and managing risk around data.  This is not a bad thing at all, since it helps keep risk management activities proportional to risk and the nature of the data.

CDO’s should approach the challenge with a plan, emphasizing transparency and engaging appropriate stakeholders.  Whereas today, Boards often look to the CIO and CISO to understand how data handled and protected, going forward they will increasingly look to the CDO.