Banner reading “Moving the Dot: Where AI pays off in a privacy program,” with a glowing dot traveling along an arc across an abstract blue network toward the J.H. logo.
CCPA, CPO, GDPR, IAPP, Privacy, Privacy & data protection, Regulatory Compliance, Risk management

Moving the Dot: Where AI Pays Off in a Privacy Program

Executive Summary

Privacy programs have never been funded for full coverage. They close the gap between what the law requires and what they can afford by accepting risk. As pressure on obligations owed to individuals and regulators rises,1 that trade-off is becoming untenable.

AI changes the equation. Applied to four foundations of the program, and built on investments the enterprise has already made plus a targeted privacy layer, it acts as a force multiplier. It lets organizations reduce the risk they accept without a proportional increase in cost, provided it is managed as a control.

What You Will Gain From This Article:

1. Why Can’t Privacy Programs Cover Everything?

Meeting every statutory obligation and addressing every inherent risk has traditionally required more people than can be cost-justified. Programs close the gap the only way they can: they cover the highest-priority obligations well and tolerate gaps elsewhere. That gap is residual risk that has been accepted, often by default rather than by decision. And where it is a decision, it is often made by people with little real choice: privacy leaders without the budget or influence to close the gap.

Over time, that acceptance drifts. The question quietly shifts from “are we compliant?” to “how likely are we to be caught, or to cause harm?” That is an enforcement calculation, not a compliance one. It is rarely made explicitly, and it rarely survives an audit finding, a regulatory inquiry or an incident.

The economics have held because the only way to add coverage was to add people. AI changes that. Work that once required headcount, such as reading, classifying, searching and drafting, can now be multiplied, so less risk has to be accepted for the same cost.
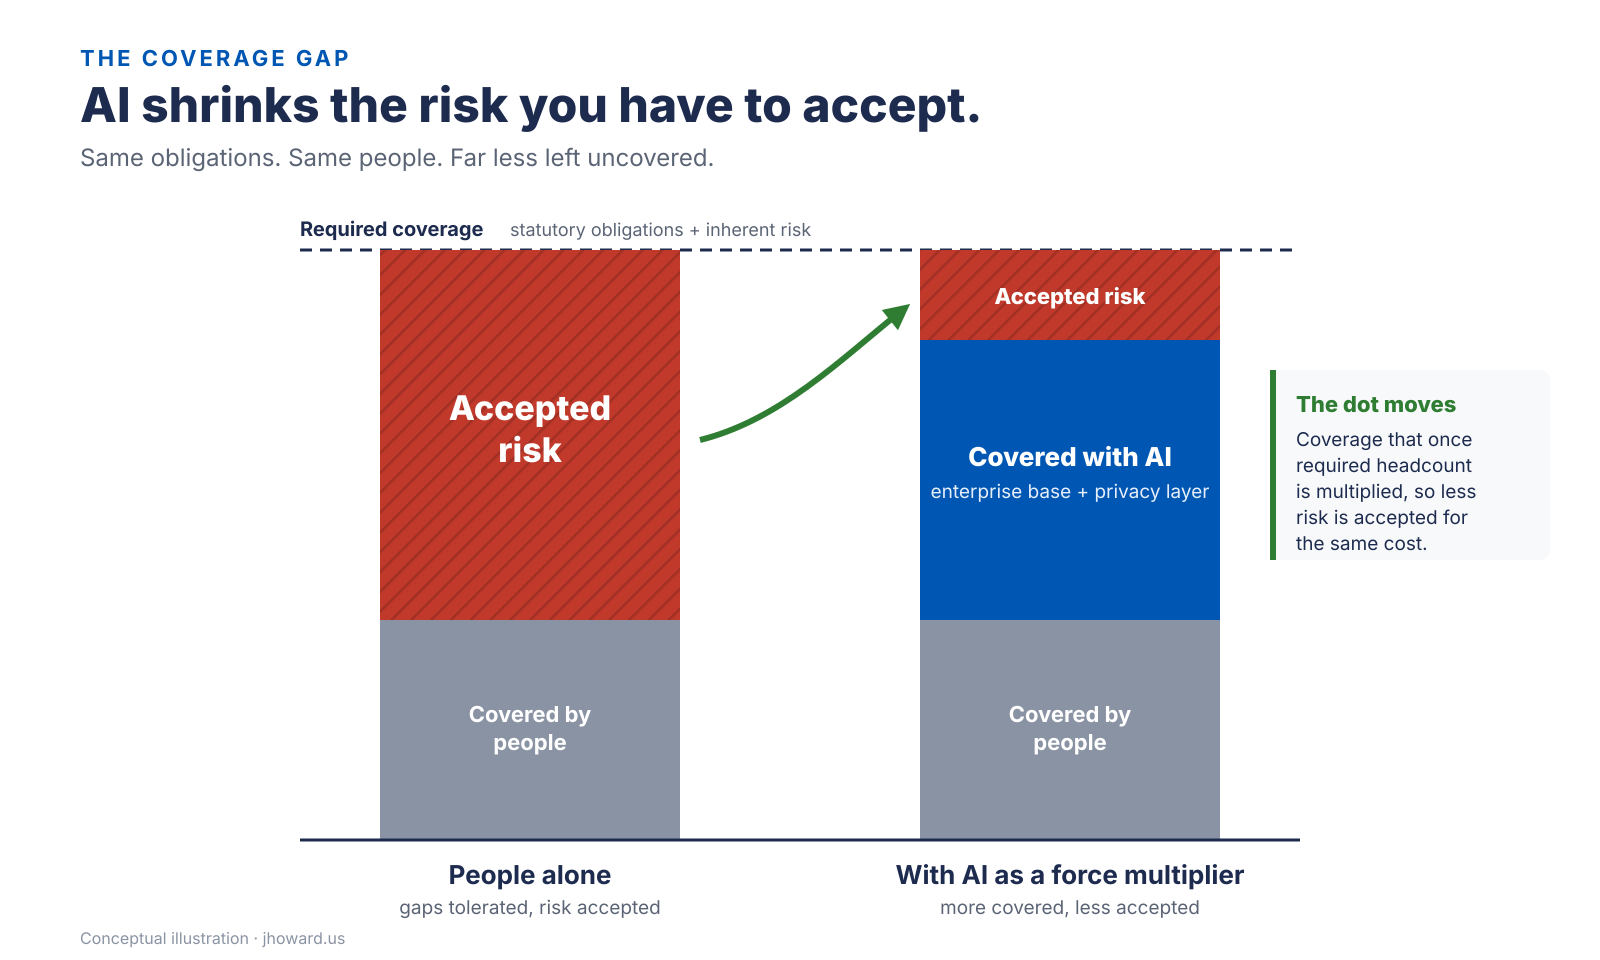
Two bars of the same required privacy coverage. With people alone, a large red block of accepted risk sits above a gray block covered by people. With AI as a force multiplier, a blue block covered with AI fills most of that space, leaving only a thin band of accepted risk.
Figure 1. The coverage gap: same obligations, same people, far less risk accepted.

2. Why Is the Gap Getting Harder to Sustain?

The gap is getting harder to sustain, particularly on the obligations side.

Rights requests are growing in volume, complexity and consequence. Individuals now use generative AI to draft long, legally sophisticated requests in seconds,2 and requests are increasingly organized: some are filed in bulk to gather material for litigation, and some opportunistically, to provoke a failure and claim compensation. Europe’s highest court confirmed in 2026 that a mishandled access request can itself give rise to compensation, even where the underlying processing was lawful.3 Every request, however it was drafted or organized, carries a deadline that runs from the day it arrives.

Incident rules keep tightening. The SEC’s amended Regulation S-P requires a written incident response program and notice to affected individuals within 30 days,4 joining the GDPR’s 72-hour regulator notification and a patchwork of state laws. Meeting those deadlines depends on knowing quickly whose data was affected and which rules apply.


3. What Are the Four Foundations, and Where Do They Sit?

Four foundations carry most of the obligations load, and they are not independent.

Two are reference foundations:

  • The data inventory tells the organization what data it holds, where it sits, and how to find a specific person’s records.
  • The rights and preferences profile tells it what each individual is entitled to and what they have chosen: consents, opt-outs, objections.

The other two are processes that depend on them:

  • Privacy by design (PbD) and privacy impact assessments govern change. PbD conveys privacy requirements before development begins, drawing on both reference foundations. The PIA confirms, after development and before launch, that those requirements were met.
  • DSR and incident response query both to define what must be searched, retrieved, disclosed or notified, and by when.
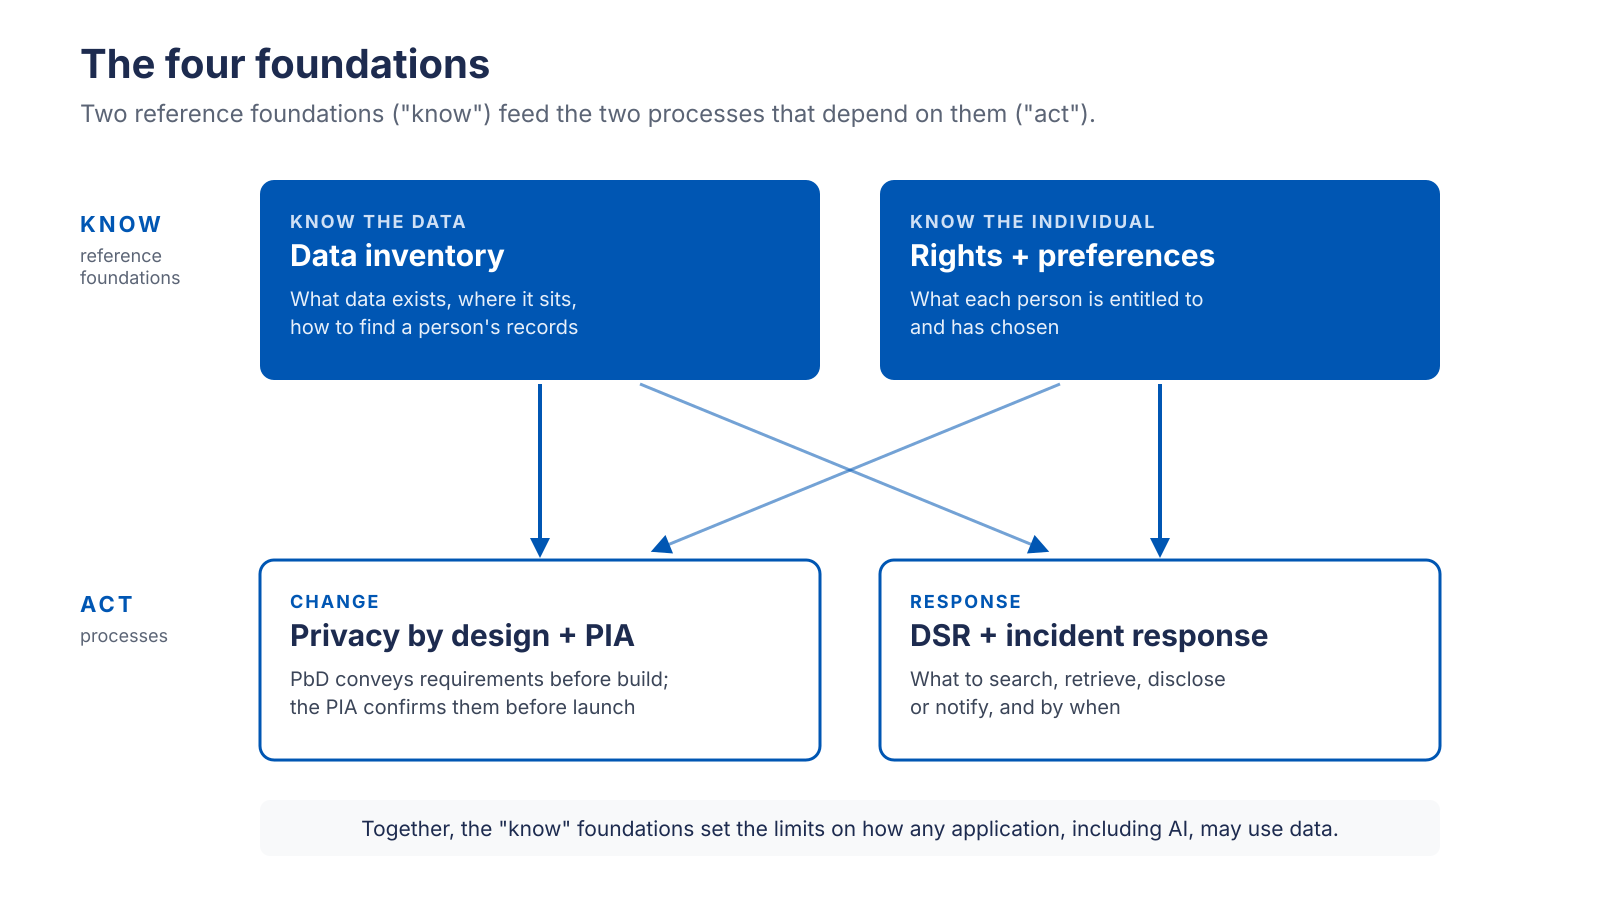
Diagram of the four foundations. Two reference foundations at the top, the data inventory (know the data) and rights and preferences (know the individual), each feed down into two processes below: privacy by design and PIA (change) and DSR and incident response (response).
Figure 2. The two “know” foundations feed the two “act” processes.

Plot each foundation by its residual risk and operating cost. Residual risk measures where each foundation sits; accepted risk is the part of it the organization is choosing to live with.

The Risk-Cost Matrix
Lower cost Higher cost
Higher risk Hidden exposures: cheap because under-resourced, not because well-run Pressure points: manual, high-volume, deadline-driven
Lower risk Steady state: standardized, automated, monitored Overbuilt: effort out of proportion to the risk it manages

In many organizations, the foundations sit like this:

  • Data inventory is often a hidden exposure: manual, rarely current, and too costly to cover the full breadth of the organization’s data. Application inventories often serve as a proxy, but their narrow view doesn’t support a common taxonomy or enterprise-wide classification.
  • Rights and preferences are often a hidden exposure, scattered across systems and markets. That’s cheap until an opt-out isn’t honored or a request is scoped incorrectly.
  • PbD and PIAs are often a hidden exposure that becomes a pressure point. Without requirements up front, issues surface late, and manual PIAs struggle to keep pace with Agile delivery. They are completed after the fact, forcing costly redesign (or more risk acceptance), or not at all, leaving a blind spot.
  • DSR and incident response are the pressure points: high-volume, deadline-driven, and inheriting every weakness in the reference foundations.

The hidden exposures are where risk acceptance lives. The pressure points are where it fails first. Rising pressure pushes every foundation up and to the right. The objective is to move them back, down and to the left.
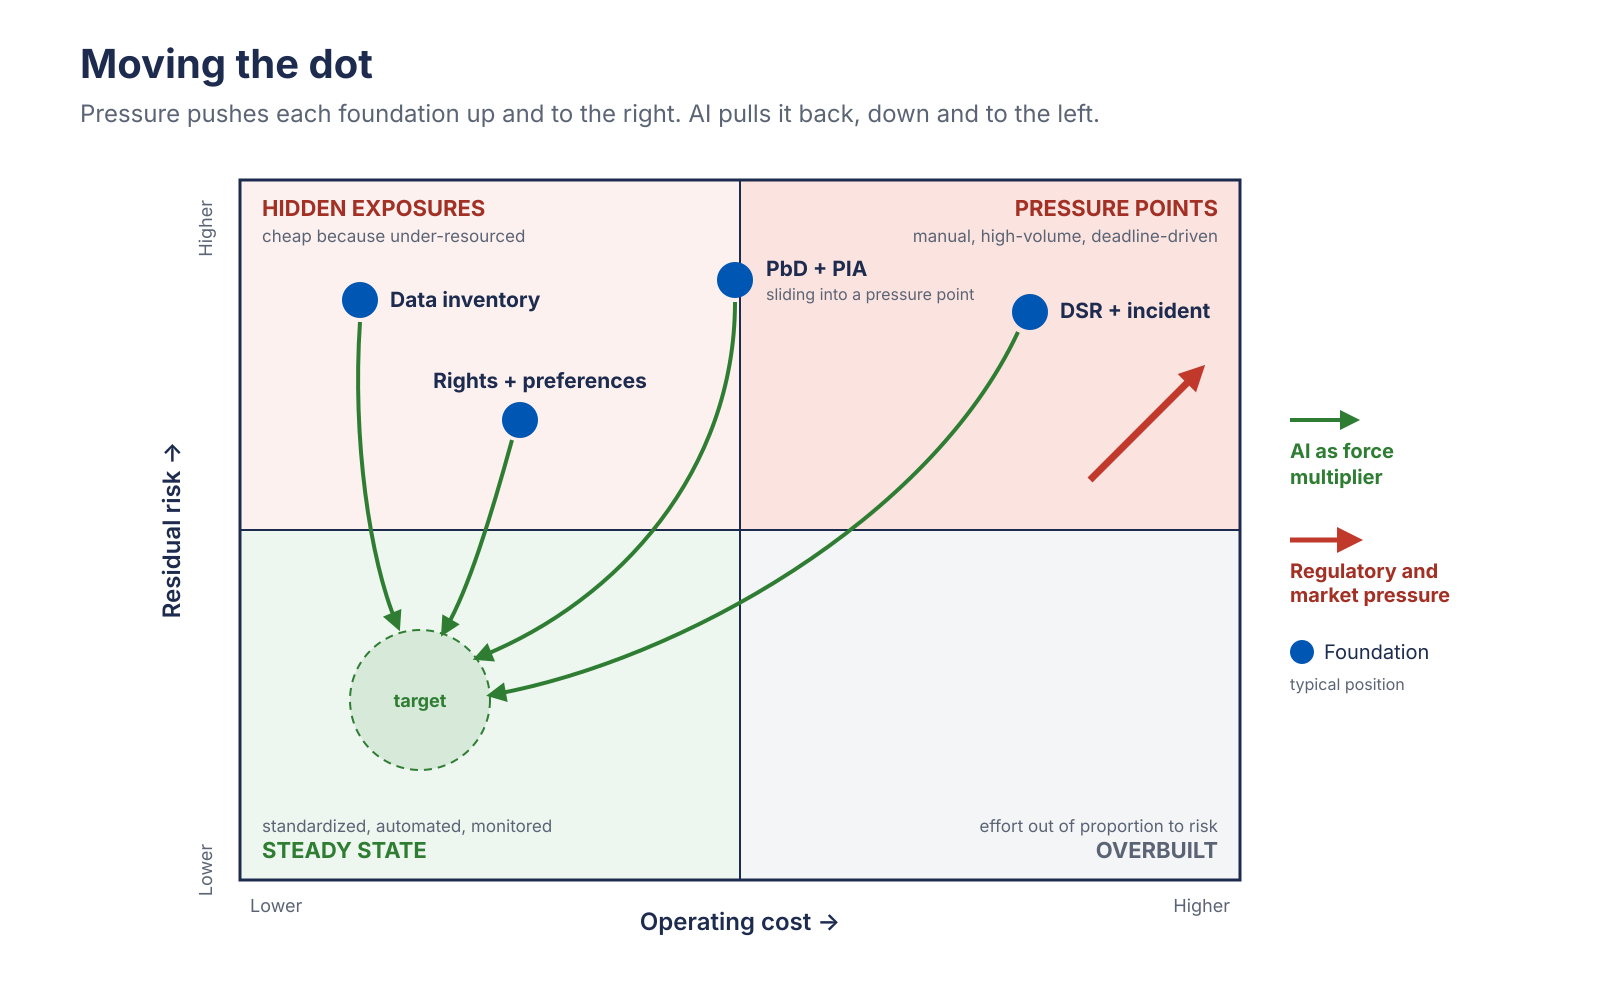
Risk-cost matrix with four quadrants: hidden exposures, pressure points, steady state and overbuilt. The data inventory and rights and preferences sit in hidden exposures, PbD and PIA on the border sliding into pressure points, and DSR and incident in pressure points. A red arrow shows regulatory and market pressure pushing up and to the right; green arrows show AI pulling each foundation toward a steady-state target.
Figure 3. Moving the dot: pressure pushes up and to the right; AI pulls back toward steady state.

4. How Does AI Change the Equation?

Most of the cost in a privacy program comes from people reading things: system documentation, call transcripts, emails, request letters, incident reports. AI is good at exactly that work. It can classify data, interpret a sprawling request, flag a likely rights request in a chat transcript, or draft a first-pass assessment, all for a person to confirm.

The enterprise is probably already paying for much of the capability. Security teams have invested in data discovery and incident management. Data teams run catalogs and lineage tools. Contact centers use speech and text analytics. Legal owns eDiscovery. Delivery teams run Agile tooling. Most organizations now license an enterprise AI platform.

But these were built for other purposes, and they rarely meet privacy’s needs on their own. A data catalog knows where data sits, not who it belongs to, what each person has permitted, or how long it may be kept. Incident management is traditionally owned by information security, with privacy running in parallel or added on afterward. The practical model is to leverage the enterprise base and add a privacy layer, which often means targeted investment in privacy management tools that bring privacy context to the platforms the organization already runs.

AI as a Force Multiplier: Leverage the Base, Add a Privacy Layer
Foundation What AI does Enterprise base to leverage Privacy layer to add
Data inventory Scans systems, classifies personal data, maps it to a common taxonomy, keeps it current Data catalogs and lineage, data security posture management, application inventories Privacy taxonomy and classification; links to individuals, purposes, legal bases and retention
Rights and preferences Interprets free-text requests and preferences, matches identities; rights determination stays rule-based Customer platforms, identity services A rights and preferences engine: jurisdictional rules, consents and opt-outs, propagated to applications
PbD and PIAs Generates requirements at intake; scans code for use of personal data and reconciles it with permitted purposes; embeds a short assessment in delivery tools; triages risk; drafts findings Enterprise AI platform, Agile and workflow tools, code repositories and CI/CD pipelines, GRC Privacy requirements library and assessment workflow integrated with delivery, linked to the inventory and rights and preferences
DSR and incident response Detects requests in calls, chats and mailboxes; automates retrieval; proposes redactions; reviews incidents for privacy impact Contact-center analytics, eDiscovery, security incident management, case management DSR orchestration; privacy impact triage and notification rules within the incident process

In each case, AI moves the foundation down and to the left: the enterprise base keeps cost down, and the privacy layer makes the risk reduction real. AI pays off first in the reference foundations, because every downstream process draws on them. Automating response on top of weak foundations simply produces wrong answers faster.

Privacy leaders see the opportunity but are moving cautiously. In a small 2026 benchmark, privacy ranked first of eleven functions on automation ambition and near last on trust in AI.5 Notably, the AI these leaders trust and use most is the AI embedded in enterprise platforms they already run, which is where the practical path begins.


5. How Should AI Itself Be Managed?

Using AI in a privacy program is defensible, and increasingly expected, but it introduces risks of its own: it processes personal data (including employees’), models make mistakes, third-party services raise disclosure and data-location questions, and AI regulation is evolving quickly.

AI is an assistant, not a decision-maker, and it must be managed like any other control:6

  • Foundations first. AI amplifies whatever it is built on.
  • Human in the loop for disclosures, denials, deletions, notifications and assessment outcomes.
  • Purpose limitation, with no drift into performance management or marketing.
  • Accountability for every AI tool: a defined role and limited permissions, a named owner, a record of what it did, and the ability to stop it quickly.
  • Architecture by design: run AI where the data already sits, and account for data location and emerging AI rules.

6. What Should Executives Do Now?

  1. Make the risk acceptance explicit, and elevate it. Identify where coverage gaps are being tolerated, whether that is a compliance decision or an enforcement calculation, and bring material acceptances to the operating or management committee and the board, where the authority to fund or accept them sits.
  2. Plot the foundations on the matrix using real indicators: request volumes, cycle times, missed deadlines, late or skipped assessments, audit findings.
  3. Inventory what you already own, and identify the privacy layer each needs: the catalog, security, analytics, eDiscovery, delivery and AI platforms the enterprise has funded.
  4. Strengthen the reference foundations first.
  5. Accelerate the pressure points with named workflows, starting with DSR and incident response and bringing PbD and PIAs onto the delivery critical path.
  6. Measure the movement: cost per request, cycle times, inventory coverage, PIAs completed before launch, and the risk no longer being accepted.

Two Questions for Boards and Audit Committees

  1. Where is our privacy program accepting risk today, and who decided?
  2. Which enterprise investments could support privacy, and what privacy layer would they need?

Conclusion: Moving the Dot

For years, privacy programs have balanced what the law requires against what they can afford, and closed the difference with risk acceptance. Rising pressure is making that balance harder to hold. AI does not eliminate the trade-off, but it changes its terms.

Built on strong foundations, investments the enterprise has already made and a targeted privacy layer, it lets organizations cover more while accepting less risk, without a matching rise in cost. Organizations that manage it well will respond faster, see their data more clearly, and earn the trust that turns privacy into a competitive advantage.


Notes

  1. This article focuses on obligations owed to individuals and regulators: rights, consent, change and incident response. Rising complexity affects program design and cost more broadly. New requirements must be translated into processes and applications across the enterprise, and programs also carry the cost of notices, third-party oversight, cross-border transfers, training and governance reporting. The same force-multiplier logic applies to many of these, but they warrant separate treatment. ↩
  2. Ireland’s Data Protection Commission reported more than 16,000 contacts in 2025, a 45% increase on the prior year, and noted that access requests are increasingly long and AI-generated. Data Protection Commission, Annual Report 2025. ↩
  3. Court of Justice of the European Union, Brillen Rottler GmbH & Co. KG v TC, Case C-526/24, judgment of 19 March 2026. The Court also held that clearly abusive requests may be refused, but only on evidence, and that refusing a first request should remain exceptional. ↩
  4. U.S. Securities and Exchange Commission, amendments to Regulation S-P (adopted May 2024). Larger covered entities were required to comply by December 3, 2025, and smaller entities by June 3, 2026. ↩
  5. Assemble, The State of AI in Data Privacy, Decision Intelligence Benchmark special report (survey of 26 data privacy leaders, February–March 2026). ↩
  6. AI proposes, people decide, accuracy is measured, and changes follow model governance. Organizations can keep AI close: on-premises, within their own cloud environment, or inside platforms they already use. They can also tailor it to internal data. Retrieval, where the model reads internal data at the moment of use, keeps personal data out of the model itself. Fine-tuning on personal data embeds it in the model, making the model a new repository that must be inventoried, secured and subject to individuals’ rights. As AI use grows, the reference foundations should extend to training data, models and agents. ↩
J. Howard logo

James I. Howard

CPO & Privacy Advisor

james@jhoward.us · More articles →

CDO, CPO, IAPP, Information Management and Governance, Information protection, Privacy, Risk management

Beyond the Blind Spots: The Efficiency Trap in Privacy Compliance for Mid-Market Companies

In the rush to scale, many companies—ranging from start-ups to mid-market enterprises—often make a pragmatic, yet perilous, decision: they treat privacy compliance as a “side desk” assignment.

Whether it lands with the CISO, the IT Director, or the General Counsel, the mandate is usually the same: “Make it work, keep it lean, and don’t let it slow us down.”

As a result, we are seeing a massive shift toward “efficiency-first” privacy. For the non-specialist leader tasked with this responsibility, the pressure is immense. To bridge the knowledge gap, many are turning to Generative AI to draft policies or manage data maps.

But there is a fundamental difference between having a policy and operationalizing a program.

The AI Mirage and the Knowledge Gap

AI is an incredible tool for documentation, but it lacks the “institutional muscle memory” required for true governance. It can’t sit in an Audit Committee meeting and explain why a specific data flow was deemed a high risk, nor can it navigate the nuance of a complex cross-border data transfer agreement.

For the CISO, IT Director or Legal Officer, relying solely on AI or automated “checkbox” software creates a false sense of security. It leaves behind “blind spots”—the operational gaps where data actually lives, moves, and leaks.

The New Frontier: Internal AI Adoption and Overlapping Risk

The challenge is no longer just about protecting static databases; it is about the explosive, often unmanaged, use of AI tools across every department. From marketing teams using LLMs for copy to engineering teams using AI to refactor code, “Shadow AI” is the new Shadow IT.

This creates a dangerous overlap between AI Risk and Privacy Risk:

  • Data Leakage: Sensitive customer data or trade secrets being used to train third-party models.
  • Algorithmic Bias: Automated decisions that may inadvertently violate privacy rights or fair-practice regulations.
  • Compliance Triggers: Under frameworks like the EU AI Act or evolving state laws, the mere use of AI often triggers mandatory Data Protection Impact Assessments (DPIAs) that most non-specialists aren’t equipped to perform.

When AI and privacy risks collide, they create a “force multiplier” for liability. You cannot govern AI without a mature privacy framework, and you cannot have a modern privacy framework while ignoring your company’s AI footprint.

Building on a Framework, Not Just a Feeling

True privacy compliance isn’t about the software you buy; it’s about the framework you build and the processes you implement. Boards and Audit Committees are increasingly looking for evidence of Operationalized Compliance:

  1. Repeatable Processes: How do you handle a DSAR (Data Subject Access Request) on a Tuesday morning without it becoming a four-department fire drill?
  2. Risk Documentation: Can you demonstrate that privacy-by-design (and AI-by-design) was considered before the new product feature was pushed to production?
  3. Vendor Governance: Do you actually know what your third-party AI and SaaS providers are doing with your data?

The Strategic Value of the Fractional CPO

For mid-market firms—and the PE/VC firms that back them—hiring a full-time, six-figure Chief Privacy Officer is often overkill. Yet, leaving a CISO or IT Director to “figure it out” increases the risk of a regulatory bottleneck during due diligence or an exit.

This is where the Fractional CPO changes the math. A Fractional CPO provides the specialized oversight of an executive-level expert at a fraction of the cost. They don’t just “check boxes”; they build the framework that allows the CISO and Legal teams to execute with confidence.

The goal isn’t just to stay out of trouble. It’s to build a high-velocity business where privacy is a fuel, not a brake.

Conclusion: Moving From Risk to Resilience

In the modern regulatory landscape, “compliance” is no longer a static destination—it is a continuous operational state. For mid-market companies, the efficiency trap of delegating privacy to overextended non-specialists or relying solely on AI tools creates vulnerabilities that only become visible when it’s too late.

By integrating fractional expertise, leadership can move beyond the blind spots. You gain the ability to navigate the complex intersection of AI innovation and data protection without the overhead of a full-time executive hire. Ultimately, operationalizing your privacy program doesn’t just satisfy auditors or investors; it builds the trust and resilience necessary to compete in an AI-driven economy.

Questions for the Board & Leadership:

  • Is our privacy lead an expert, or a generalist wearing too many hats?
  • Do we have a clear inventory of where AI is being used and what data is being shared with it?
  • If a regulator knocked tomorrow, could we show an operationalized process, or just a folder of AI-generated PDFs?
  • Are we leveraging fractional expertise to de-risk our upcoming exit or audit?
CCPA, CDO, CPO, GDPR, IAPP, Privacy, Risk management

Building a Simplified Privacy Program in Business

The rules around protecting the privacy of customer and employee data are becoming one of the most complex business risks (not necessarily highest risk). With no single federal law, organizations face a complicated patchwork of state regulations (like those in California and Virginia), all while new Artificial Intelligence (AI) rules are beginning to overlap and add even more complexity.

This paper cuts through that complexity. It presents a simple, practical framework for a modern privacy program, focusing on the essential “what” must be achieved, not the highly detailed “how.” The goal is a program that is easy to understand, aligned with business strategy, and nimble enough to keep up with the law.

Three Pillars of a Resilient Privacy Program

To ensure continuous compliance, managing risk, and ready to respond, privacy programs can be thought of as built on three essential, functional pillars: Steady State, Change Management, and Response.

I. Steady State: The Foundation of Continuous Compliance

This pillar is about maintaining a clear, current understanding of what data is on hand and what can be donr with it. It focuses on the recurring activities that maintain compliance day-to-day.

Key ComponentWhat It Does for the Business
Inventory of Data and ProcessesWhat personal data is collected, why, and where is it stored. What permissions are attached to it? This is the single most critical piece of information, as it dictates all other requirements (e.g., disposal deadlines, security needs).
Inventory of ObligationsA clear view is needed of all applicable regulatory requirements (e.g., state laws) and contractual agreements (e.g., what promises are made to clients or what vendors commit to do).
Third-Party Risk Management (TPRM)Vendors and partners are a disproportionate source of privacy risk. A formal process is needed to assess how they handle data, which is often overlooked in favor of standard IT security checks.
Risk and ControlsAreas of greatest exposure must be identified and proportionate safeguards in must be put in place. This includes employee training and technical controls to limit who can access sensitive data.
Incident ResponseA formal plan for responding to privacy breaches or misuse of data is essential. This allows for quick action, remediation of vulnerabilities, and the ability to meet strict regulatory notification deadlines to minimize reputational and financial harm.

II. Change: Integrating Privacy by Design

This pillar proactively manages new risks that emerge in connection with new products, services, or large projects. It ensures that privacy is a fundamental design element, not a reactive checklist at the end.

Key ComponentWhat It Does for the Business
Privacy Impact Assessments (PIAs)This is the mandatory checkpoint for “Privacy by Design.” It’s a formal analysis to determine if a new initiative poses a high risk, ensuring the Privacy team is engaged early in the development cycle, long before launch.
Regulatory Change ManagementThe legal landscape is constantly changing. It suggests a formal process to monitor new laws, determine their impact, and implement necessary control changes before they take effect.
Process and Control ChangesA mechanism to engage the privacy team when business or IT process changes impact how personal data is handled. This prevents unauthorized, or “shadow,” changes from introducing new vulnerabilities.

III. Response to Inquiry: Demonstrated Accountability

This pillar focuses on the auditable evidence and response mechanisms that prove the program is working and demonstrate transparency to both regulators and data subjects (i.e., customers/employees).

Key ComponentWhat It Does for the Business
Data Subject Rights (DSR) ManagementPeople have a legal right to ask us what personal data an organization has have on them and how they’re using it.  This drives the need for a streamlined, auditable workflow to intake these requests, verify identities, and fulfill them within strict regulatory deadlines.
Regulator RequestsOn occasion, a regulator may inquire about a privacy program. Having a clear response plan is necessary to efficiently provide the required evidence and documentation, often leveraging the data from the Inventory and the DSR process.
Measurement and Continuous ImprovementTracking certain operational metrics is key (e.g., number of incidents, time to fulfill DSRs) to monitor the effectiveness of the program and identify areas that require management focus and resource investment.

Executive Summary

The growing complexity of US privacy law demands a highly organized and resilient compliance framework. To navigate this challenge, we must focus on structure (the three functional pillars), process management, and enabling technology.

By proactively investing in and leveraging specialized privacy technology platforms, management of these intricate requirements can be automated. This approach achieves defensible compliance while keeping operational costs managed, allowing the business to drive forward with reduced risk.

CPO, Privacy, Uncategorized

Overcoming the Privacy Complexity Trap: Right-Sizing Privacy for Strategic Advantage

The modern corporate privacy program, especially within mid-size enterprises, has inadvertently evolved into a major source of operational complexity, frustration and friction, often disproportionate to the actual regulatory risk it seeks to mitigate. Instead of being designed as a streamlined risk management function, programs frequently become bloated, slow, with checklist-driven mandates built to satisfy the compliance demands of every fragmented state law individuallyand equally. This approach leads to “checklist paralysis,” diverting excessive time and budget towards documentation and reviews rather than focusing resources on the small subset of truly high-risk, sensitive data—the company’s “crown jewels.” The result is a system that is overly expensive, strategically inflexible that creates tension between the mission-oriented departments (development, sales, delivery) and the control-oriented groups (risk, compliance, legal).

To combat this complexity, organizations must pivot from a purely centralized compliance model to a hybrid that includes distributed, risk-balanced privacy program execution. This alternative design requires strategically moving certain privacy activities out of a central department and embedding them within the business functions that create, gather, storeand process data.

The foundation of this distributed model rests on three pillars of activity across the organization:

  1. Strategic Governance (Central Team): The central function shrinks to focus only on program stewardship, high-level policy, external regulatory change monitoring, risk modeling, and overall accountability. It defines the “what” and “why.”
  2. Embedded Privacy-by-Design (Engineering/Product): Department-level individuals are trained to own the initial privacy decisions (with consultation where necessary). They are responsible for implementing data protection, data minimization and purpose limitation controls at the system design level, making the program proactive rather than reactive. This operationalizes the core tenets of the principles-based framework directly into the creation of new products and services.
  3. Automated Execution (Operations/IT): This is where Privacy Management Platforms (PMPs) become the essential enabler of the right-sized program. Cloud-based PMPs distribute the workload for high-volume, repetitive, and resource-intensive tasks without distributing the risk.

By leveraging these platforms, a company can automate the most common compliance burdens: maintaining automated data inventories, standardizing and deploying consent banners, and managing the workflow for Data Subject Access Requests (DSARs). This automation drastically reduces the risk and the need for expensive, manual labor—the biggest driver of complexity and cost—allowing the distributed staff to focus on genuine innovation and high-value risk mitigation.

In conclusion, right-sizing a privacy program requires a strategic trade-off: trading centralized control for decentralized accountability, and trading manual compliance for automated execution. This approach removes unnecessary friction, lowers operational costs, and transforms privacy from a bureaucratic hindrance into a sustainable, competitive edge that fosters enduring customer trust.